


The Zhitong Finance App learned that CITIC Construction Investment released a research report saying that DeepSeek updated the Flash model to improve programming and automated task performance while maintaining low prices, and open up search and content capture capabilities; in addition, Zhitong published a law-specific model to gradually disclose long-term agent training plans. Improvements in domestic model capabilities, call costs, and tool support are expected to expand the scope of application of agents in code development, data analysis, and enterprise business systems, and drive the growth of enterprise workflow applications and inference requirements. It is recommended to focus on enterprise-level AI applications, computing power services, and domestic chips and supernodes.
CITIC Construction Investment's main views are as follows:
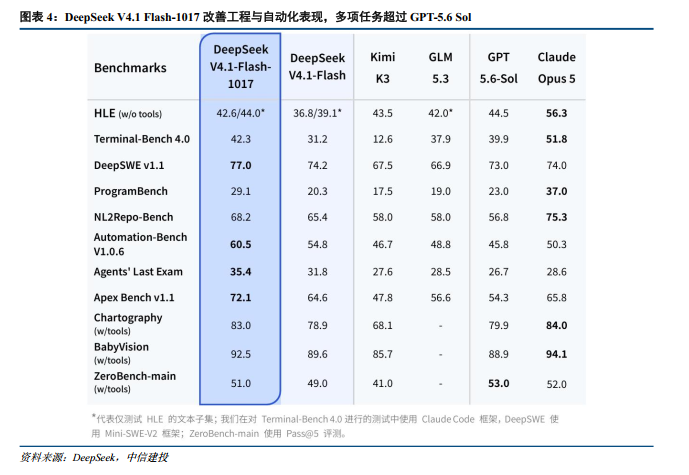
DeepSeek updated the Flash model and improved programming and agent task capabilities. On October 17, DeepSeek released v4.1-Flash-1017. The official website, app, and API were switched synchronously, and the API call method and price remained the same. Based on V4.1 Flash released on September 10, this update improves inference, programming, automation, and visual task performance, and is optimized for frameworks such as DeepSeek Harness, Tencent CodeBuddy, and WorkBuddy. V4.1 Flash focuses on efficient and low-cost usage, and this upgrade further expands the range of engineering tasks it can undertake. Through reinforcement learning based on self-feedback, the company enhances the model's ability to build a complete project from requirements description, and showcased 3D modeling, web games, and Godot-based game development cases. Application capabilities extend from code generation to tool call, result inspection, and multiple rounds of correction.
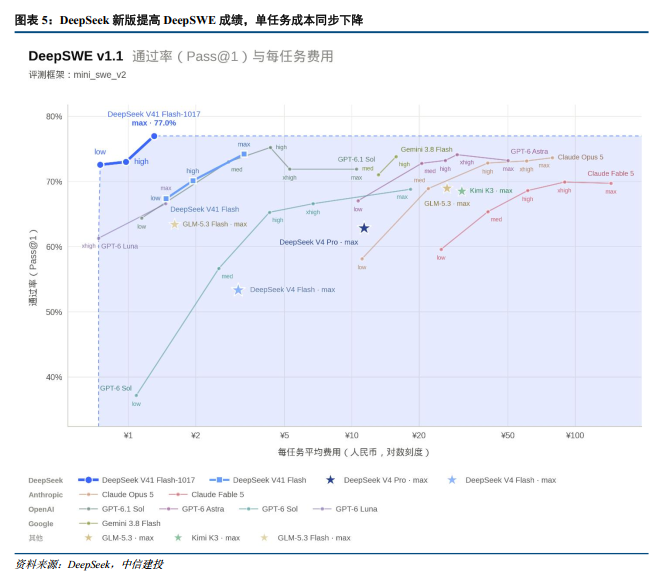
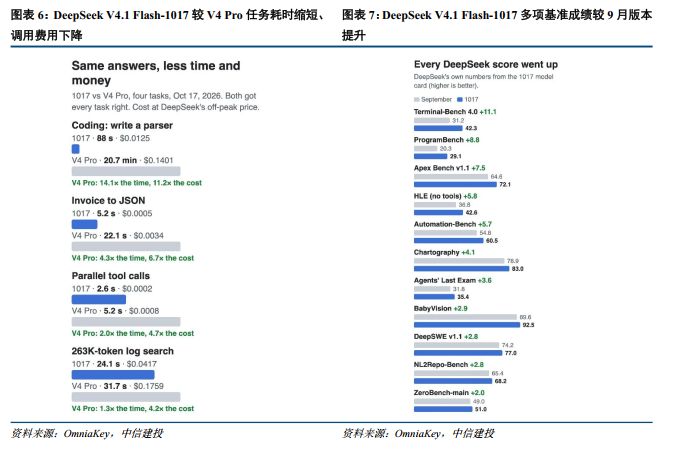
Engineering and automation evaluations have improved markedly, and the performance of some tasks surpassed GPT-5.6 Sol. According to the evaluation published by DeepSeek, the new DeepSWE v1.1 results increased from 74.2% to 77.0%; GPT-5.6 Sol and Claude Opus 5 were 73.0% and 74.0% respectively; Terminal-Bench 4.0 increased from 31.2% to 42.3%, GPT-5.6 Sol was 39.9%; Automation-Bench increased from 54.8% to 60.5%, and GPT-5.6 Sol was 45.8%. Among them, terminal task performance increased by 11.1 percentage points, which is a significant improvement. Advances in code engineering, terminal execution, and automation tasks help cover the daily work of more developers at a lower cost, and provide support for domestic cost-effective models to enter the actual workflow.
API prices remain low, and low-cost calls support the expansion of agent tasks. As of October 18, the official DeepSeek price shows that the new version is $0.15 and $0.60 for each million missed cache input and output tokens during the off-peak period, $0.30 and $1.20 respectively during peak periods; $0.003 and $0.006, respectively. The current discounted price of GPT-5.6 Sol in the standard short context is $4 per million for input and $20 for output. Comparing DeepSeek's peak buffer prices, the unit prices for input and output are 92.5% and 94% lower, respectively. Long-term agents require repeated code reading, processing tool results, and multiple rounds of inference. Lower input, cache, and output prices help application vendors increase task testing, deploy parallel agents, and expand automation capabilities to more high-frequency scenarios.
Independent experiments reflect the cost performance ratio of programming, and the efficiency of the base model affects the cost of completing the task. Developer Ibragim Badertdinov updated the personal programming evaluation on October 17, selected 10 daily engineering tasks, repeated each configuration 3 times, and checked the results through hidden tests. Under the Pi framework, DeepSeek V4.1 Flash-1017 passed all 30 high speed runs, with an average cost of $0.045 per task; GPT-5.6 Sol Medium's pass rate in the same table was 96.7%, with an average cost of 0.2017 dollars, and the cost of the new version was about 77.7% lower. The GPT-6 Luna XHigh also passed all. The average token consumption per task was 290,000, lower than DeepSeek's 547,000, and the cost was 0.0145 US dollars, reflecting differences in efficiency under different base models and inference configurations. Another set of tests announced by OmniaKey on October 18 compared the new version with the V4 Pro. Both models achieved correct results in four common tasks, and the new version reduced both time and cost. Among them, the invoice to JSON tasks all correctly extracted 10 fields. The new version took 5.2 seconds and cost 0.0005 US dollars, and the V4 Pro was 22.1 seconds and 0.0034 US dollars respectively; the time required for about 260,000 token log retrieval tasks was shortened from 31.7 seconds to 24.1 seconds, and the cost was reduced from $0.1,759 to $0.0417. Two sets of experiments showed that the Flash version already has good economics for everyday tasks, and subsequent iterations of the flagship model are expected to further improve complex task capabilities and reasoning efficiency.
DeepSeek opens search and retrieval capabilities, models and tools to collaborate to reduce agent access costs. On October 17, DeepSeek opened self-developed search and fetch interfaces to provide developers with web search and content scraping capabilities. Based on this, the model can obtain external information, read web content, and complete continuous tasks in combination with code execution and file processing. The scope of application extends from offline Q&A to networked research, data analysis, and engineering development. Both interfaces are billed at $0.75 per 1,000 successful requests. When using the DeepSeek API through DeepSeek Harness, Claude Code, and Codex, there is no charge for related server calls. Billing starts on November 1, Beijing time. The company simultaneously optimizes mainstream programming and office agent frameworks, and opens the weight of the MIT license model, which helps developers to use existing tools to access, and also provides a foundation for enterprises to build their own deployments and customize scenarios.
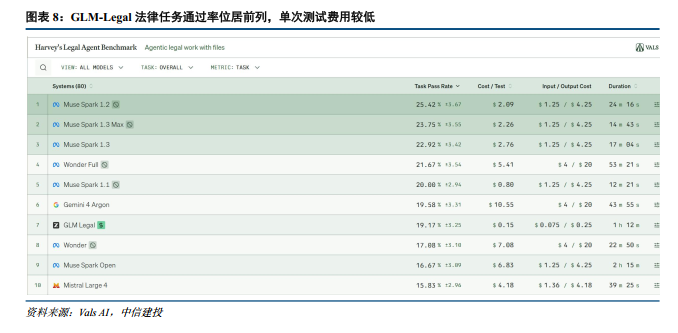
Smart Spectrum publishes law-specific models, and professional training enhances complex business delivery capabilities. On October 12, Smart Spectrum released GLM-Legal based on GLM-5.3-Flash for legal work such as contract review, evidence analysis, and compliance research. Through mid-term legal literature training and intensive learning in tens of thousands of real legal task environments, the model learns material retrieval, legal analysis, and document delivery, and simultaneously optimizes the agent framework responsible for context management, tool call, and execution feedback. According to the company's disclosure, GLM-Legal's overall pass rate in the Harvey Legal Agent evaluation reached 19.2%, an increase of 12.5 percentage points over the basic model. The independent evaluation agency Vals announced a score of 19.17%, and the cost of a single test was 0.15 US dollars. At the time of the evaluation update on October 12, it ranked 7th and the lowest in the top ten. Joint optimization of expertise, task environment and execution framework is expected to drive efficient domestic models into legal and other professional service processes.
Step by step discloses the long-range agent training plan, and the model architecture and task environment are collaboratively optimized. On October 15, Step Star revealed the structure and training details of Step 5 Preview. The model uses a mixed expert architecture with 600 billion total parameters and 27 billion activation parameters, supports up to 1 million token contexts, and targets code engineering, professional knowledge work, and multiple rounds of tool call tasks. The company built a million-level verifiable training environment around long-range tasks, covering scientific reasoning, software engineering, machine learning R&D and professional work, and incorporated task duration, cross-file modification depth, and verifiability of results into the training design. The model also organizes phased work into a recoverable state through the context compression mechanism of end-to-end training, and supports continuous execution of tasks across a single context window. Relevant developments show that the training investment of domestic models extends to the actual task environment and complete execution process, which is expected to improve the ability to complete complex engineering tasks.
Risk warning:
The risk of bad debts in accounts receivable; increased competition in the industry; the impact of changes in the international environment.